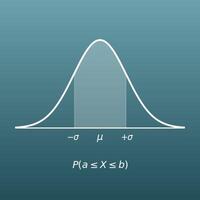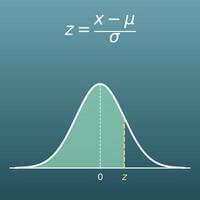
Fill in only one field, either Z (the test statistic) or one of the five probabilities. All the other values are calculated (it converts both ways, from Z to a p-value and from a p-value to Z).
Table of Contents
-
What you can do on this page
-
What is this calculation used for?
-
How to Use
-
Formula and graph
-
Symbols and terms
-
Good to know before you start
-
How to calculate it in Excel
-
How to calculate it in Google Sheets
-
How to calculate it in Python
-
How to write it in LaTeX and other math languages (copy and paste)
-
How to have ChatGPT do the calculation
-
DataChef Features
-
Related Features
-
NumberChef Calculators List
What you can do on this page
- Enter the test statistic Z from a z-test or similar, and get the p-values for left-tailed, right-tailed and two-tailed tests in one go
- Also work back from a p-value to Z (for example, find Z = 1.96 for a two-tailed p-value of 0.05). This is handy for finding the edge of the rejection region (the critical value)
- The probabilities "between 0 and Z" and "between −Z and Z" are shown too, so it also works as a replacement for a standard normal table (z table)
- A plain-language explanation of the formulas and copy-and-paste formulas for Excel, Google Sheets and Python are all on this page
What is this calculation used for?
Clinical studies of a new drug use a hypothesis test to check "is the difference between the group that took the drug and the group that did not within the range of chance?", and the p-value is the evidence for that decision. For example, a test statistic of \(Z = 2.5\) gives a two-tailed p-value of about 0.012, which reads as "if the drug had no effect, the chance of seeing a difference this large is about 1.2%".
Medical papers around the world report effects this way. Knowing what a p-value is lets you read health news one step deeper (real medical decisions are made by experts who weigh not only the p-value but also the size of the effect and the side effects).
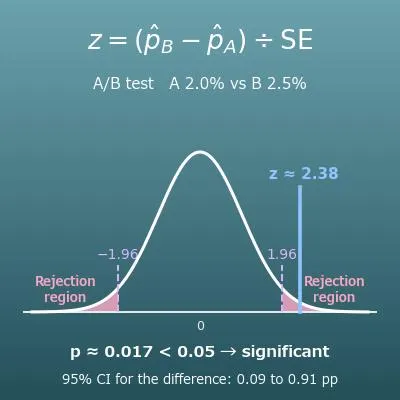
"We changed the button color and the click-through rate went up. But was it just chance?" The test in an A/B test answers that. For example, a test statistic of \(Z = 2.17\) gives a two-tailed p-value of about 0.03, which is smaller than the 0.05 significance level, so you can conclude "an improvement that is hard to explain by chance".
Online companies use this p-value every day to decide whether to adopt changes in design and wording.
Data from sample inspections is tested to see whether the average weight or size of products has drifted from the target. For example, a test statistic of \(Z = 2\) gives a two-tailed p-value of about 0.046, so at the 5% significance level you conclude "something has changed in the process" and look for the cause.
The strength of the p-value is that it separates "random variation" from "a real problem", so the decision to stop a machine can be made with numbers, not by feel.
Research papers are full of phrases such as "significant at p < 0.05" and "p = 0.003". In a two-tailed test, p < 0.05 matches "\(|Z|\) is greater than 1.96", and p < 0.01 matches "greater than about 2.58".
Knowing this link helps you report statistical results correctly in term papers and theses, and makes it easier to keep in mind a key point for reading papers: "significant" is not always the same as important (the size of the difference is a separate question).
A hypothesis test can also check whether a change such as "presidential approval is up 2 points from last month" is a real change or just the variation (error) of the poll. For example, a test statistic of \(Z = 1\) gives a two-tailed p-value of about 0.32, "about 1 time in 3 by chance even with no real difference", so it is natural to call it within the margin of error.
It is a handy, everyday way of thinking with statistics: before getting excited or worried about numbers in the news, ask "is that difference significant?".
Formula and graph
Symbols and terms
Symbols
| \(P\) | pee | The p-value: the probability of getting, by chance, a result at least as extreme as the one observed, assuming the null hypothesis is true. The smaller it is, the harder it is to explain the result by chance. |
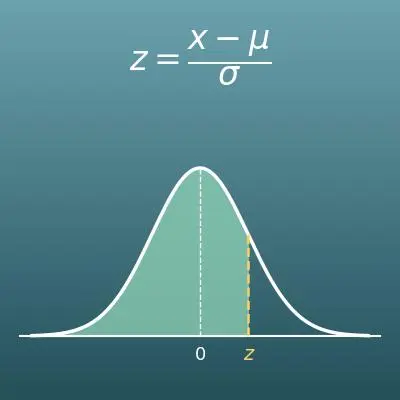
| \(Z\) | zee | The test statistic (the z value), calculated from the data and treated as following the standard normal distribution. This page finds p-values from Z. Calculating a z-score itself is covered in the related page, the z-score calculator. |
| \(\Phi(Z)\) | phi of Z | The cumulative distribution function of the standard normal distribution (mean 0, standard deviation 1). It returns the probability of a value below \(Z\), which is the area under the curve to the left of \(Z\). |
| \(\Phi^{-1}\) | phi inverse (inverse of Φ) | The function that works the other way from \(\Phi\). It takes a probability (area) and returns the Z that gives it. This calculator uses it to work back from a p-value to Z. (Example: \(\Phi^{-1}(0.975) \approx 1.96\)) |
| \(|Z|\) | absolute value of Z | The size of \(Z\) without its sign. A two-tailed test counts a gap on the plus side and on the minus side as the same "extremeness", so it uses the absolute value. (Example: \(|-1.5| = 1.5\)) |
| \(\alpha\) | alpha | The significance level: the cutoff probability you set in advance, as in "reject the null hypothesis if the p-value is at or below this". By convention, 0.05 (5%) and 0.01 (1%) are common. |
Terms
| p-value | The probability of getting a result at least as extreme as the one observed, assuming the null hypothesis is true. The smaller the p-value, the harder it is to believe the result came about by chance, and the stronger the grounds for rejecting the null hypothesis. |
| hypothesis test | A procedure that first assumes "there is no difference", measures with a p-value how unlikely the actual data would be under that assumption, and decides whether to throw the assumption out. It works much like proof by contradiction - if something very rare happened, doubt the starting assumption. |
| null hypothesis | The default assumption you want to disprove, such as "there is no difference between the two groups" or "there is no effect". The p-value is calculated on the assumption that the null hypothesis is true. |
| alternative hypothesis | The claim opposite to the null hypothesis ("there is a difference", "there is an effect"). It is the hypothesis accepted when the null hypothesis is rejected. |
| significance level | The cutoff probability for rejecting the null hypothesis, written \(\alpha\) (alpha). The rule is to set it before running the test, and 0.05 is the most widely used. If the p-value is at or below the significance level, the result is called "statistically significant". |
| reject | To throw out the null hypothesis as "hard to believe" based on the test. You reject it when the p-value is at or below the significance level. Note that failing to reject does not say "the null hypothesis is true"; it only says "there is not enough evidence to reject it". |
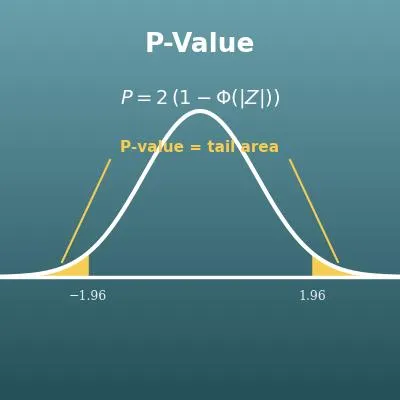
| two-tailed test | A test that treats a gap in either direction, too large or too small, as a difference. The p-value is the sum of the areas in both tails of the distribution. It is the standard choice when you cannot decide the direction in advance. |
| one-tailed test | A test that looks at gaps in only one direction, only larger (right-tailed) or only smaller (left-tailed). It is used when theory tells you the direction in advance, and the p-value is the area in that one tail only. |
| test statistic | The value calculated from the data for a test. In a z-test, it is put in a form treated as following the standard normal distribution (the z value), which tells how many standard deviations the result is from the mean. |
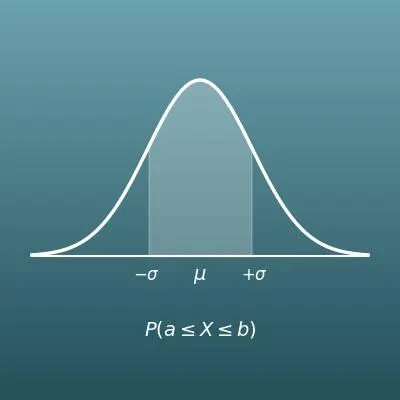
| standard normal distribution | The normal distribution with mean 0 and standard deviation 1 (a symmetric bell shape). The area under the curve is the probability, and the total area is exactly 1. The p-value of a z-test is calculated as the area in the tails of this distribution. |
| critical value | The boundary value of the test statistic beyond which you reject the null hypothesis. For a two-tailed test at the 5% significance level it is \(|Z| \approx 1.96\), and at 1% it is \(|Z| \approx 2.576\). You can check these by working back from a p-value to Z with this calculator. |
Good to know before you start
Here is what helps you use the calculation on this page with real understanding, not just by pressing the button.
| Basic probability (Grade 7) |
|
| Data analysis and standard deviation (high school statistics) |
|
| The normal distribution and reading areas (high school statistics / AP Statistics) |
|
| The idea of hypothesis testing (AP Statistics) |
|
How to calculate it in Excel
| Z (test statistic) | -1.5 |
| Left-tailed P(x<Z) | =NORM.S.DIST(B1,TRUE) |
| Z (test statistic) | 2 |
| Right-tailed P(x>Z) | =1-NORM.S.DIST(B1,TRUE) |
| Z (test statistic) | 1.96 |
| Two-tailed p-value | =2*(1-NORM.S.DIST(ABS(B1),TRUE)) |
"NORM.S.DIST(value, TRUE)" is the function for the cumulative distribution function \(\Phi\) (the area to the left of Z), and TRUE tells it to "return the cumulative value (the area to the left)". "ABS" returns the absolute value (the size without the sign).
The first table shows about 0.0668 (about 6.7%) in B2, the second about 0.02275 (about 2.3%), and the third about 0.05 (5%). Just replace B1 with your own Z.
To go the other way, "from a p-value to Z", use "=NORM.S.INV(probability)" (example: the Z for a two-tailed p-value of 0.05 is `=NORM.S.INV(1-0.05/2)`, about 1.95996).
How to calculate it in Google Sheets
| Z (test statistic) | -1.5 |
| Left-tailed P(x<Z) | =NORMSDIST(B1) |
| Z (test statistic) | 2 |
| Right-tailed P(x>Z) | =1-NORMSDIST(B1) |
| Z (test statistic) | 1.96 |
| Two-tailed p-value | =2*(1-NORMSDIST(ABS(B1))) |
The results are the same as in the Excel version: about 0.0668 in the first table, about 0.02275 in the second, and about 0.05 in the third.
To find Z from a p-value, use "=NORMSINV(probability)" (example: `=NORMSINV(1-0.05/2)` is about 1.95996).
How to calculate it in Python
import math

def phi(z):
    # Cumulative distribution function of the standard normal distribution, Φ(z) (calculated with the error function erf)
    return 0.5 * (1 + math.erf(z / math.sqrt(2)))

z = 1.96  # Z (test statistic)

p_left = phi(z)                       # left-tailed p-value P(x<Z)
p_right = 1 - phi(z)                  # right-tailed p-value P(x>Z)
p_two_sided = 2 * (1 - phi(abs(z)))   # two-tailed p-value

print(f"Left-tailed p-value: {p_left}")
print(f"Right-tailed p-value: {p_right}")
print(f"Two-tailed p-value: {p_two_sided}")
How to write it in LaTeX and other math languages (copy and paste)
P = Φ(Z)
P = \Phi(Z)
<math xmlns="http://www.w3.org/1998/Math/MathML" display="block">
<mrow>
<mi>P</mi>
<mo>=</mo>
<mi>Φ</mi><mo>(</mo><mi>Z</mi><mo>)</mo>
</mrow>
</math>
P = Phi(Z)
CDF[NormalDistribution[0, 1], z]
with(Statistics): CDF(RandomVariable(Normal(0, 1)), z);
p = normcdf(z);
P = Φ(Z)
P = 1 − Φ(Z)
P = 1 - \Phi(Z)
<math xmlns="http://www.w3.org/1998/Math/MathML" display="block">
<mrow>
<mi>P</mi>
<mo>=</mo>
<mn>1</mn>
<mo>−</mo>
<mi>Φ</mi><mo>(</mo><mi>Z</mi><mo>)</mo>
</mrow>
</math>
P = 1 - Phi(Z)
1 - CDF[NormalDistribution[0, 1], z]
with(Statistics): 1 - CDF(RandomVariable(Normal(0, 1)), z);
p = 1 - normcdf(z);
P = 1 - Φ(Z)
P = 2(1 − Φ(|Z|))
P = 2\left(1 - \Phi(|Z|)\right)
<math xmlns="http://www.w3.org/1998/Math/MathML" display="block">
<mrow>
<mi>P</mi>
<mo>=</mo>
<mn>2</mn>
<mo>(</mo>
<mn>1</mn>
<mo>−</mo>
<mi>Φ</mi><mo>(</mo><mo>|</mo><mi>Z</mi><mo>|</mo><mo>)</mo>
<mo>)</mo>
</mrow>
</math>
P = 2(1 - Phi(|Z|))
2 (1 - CDF[NormalDistribution[0, 1], Abs[z]])
with(Statistics): 2*(1 - CDF(RandomVariable(Normal(0, 1)), abs(z)));
p = 2*(1 - normcdf(abs(z)));
P = 2(1 - Φ(|Z|))
How to have ChatGPT do the calculation
You are a statistics calculation assistant. Do the following calculation by actually running Python code, and base your answer only on the numbers from the execution result (do not answer by mental math or guessing).

A z-test gave a test statistic of Z = 2.5. Assume the test statistic follows the standard normal distribution (you may use Python's standard library, such as math.erf or statistics.NormalDist).
Find each of the following:
1. The left-tailed p-value P(x<Z)
2. The right-tailed p-value P(x>Z)
3. The two-tailed p-value P(x<−Z or x>Z)
4. Whether the null hypothesis can be rejected in a two-tailed test at the 0.05 significance level

Show the formulas you used and the numbers from the execution result.
How to Use
-
1Enter your numbersType the numbers you want to calculate with into the input fields
-
2CalculatePress the "Calculate" button
-
3Check the resultThe result appears on the spot. The same page also explains the idea behind the calculation and the formula
DataChef Features

No technical knowledge required.
Intuitive and user-friendly operation.
Can be used without registering personal information.
Automatic file deletion by clicking "download".
and rapid file conversion.
No attribution required.
No need to contact us for commercial use permission.
Related Features
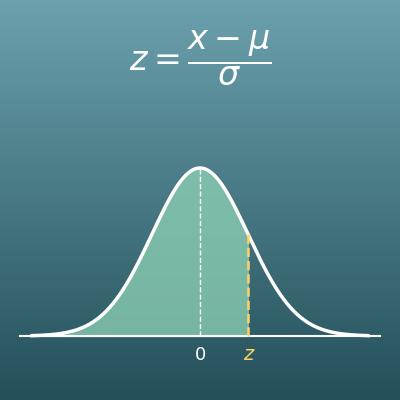
Z-Score Calculator: Z-Score to Probability and Back
Find the z-score from a value, mean and standard deviation. It also works as a replacement for a z table
Normal Distribution Probability Calculator
From the mean and standard deviation, find the probability of falling in a range or the top what percent
Confidence Interval Calculator for a Population Mean
Find the confidence interval for the population mean from the sample mean, standard deviation and sample size