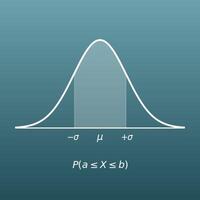
There are three ways to use this calculator. ① Find the z-score from a value, the mean and the standard deviation. ② Convert between a z-score and a probability (fill in just one field). ③ Find the probability between two z-scores. Fill in only the fields of the group you want to use.
Table of Contents
-
What you can do on this page
-
What is this calculation used for?
-
How to Use
-
Formula and graph
-
Symbols and terms
-
Good to know before you start
-
How to calculate it in Excel
-
How to calculate it in Google Sheets
-
How to calculate it in Python
-
How to write it in LaTeX and other math languages (copy and paste)
-
How to have ChatGPT do the calculation
-
DataChef Features
-
Related Features
-
NumberChef Calculators List
What you can do on this page
- Enter a value \(x\), the mean \(\mu\) and the standard deviation \(\sigma\), and you get the z-score (standard score) and the probability of a value below it in one go
- Instead of looking up a z table (standard normal table), convert between z-scores and probabilities in either direction (z-score to probability, or probability back to z-score)
- Also find the probability between two z-scores (for example, between −1.96 and 1.96) on the spot
- A plain-language explanation of the formulas and copy-and-paste formulas for Excel, Google Sheets and Python are all on this page
What is this calculation used for?
On a test with a mean of 65 and a standard deviation of 5, a score of 75 is \(z = 2\). If the scores follow a normal distribution, that puts you in about the top 2.3% (\(1 - \Phi(2) \approx 0.0228\)), which is roughly the 97.7th percentile. IQ scores are built directly from z-scores (IQ \(= 100 + 15 \times z\)), so an IQ of 130 is the same position.
This is the most familiar use of z-scores: turning a raw score into a percentile, and reading how big a gap of a few points really is, even between tests with different maximum scores and averages.
"80 in English (mean 70, standard deviation 10)" and "65 in math (mean 50, standard deviation 15)" look like English is higher on raw scores, but as z-scores both are \(z = 1\), the same position.
Even when units, maximum scores or grading strictness differ, z-scores let you compare fairly by "how far above the group" a score is. The same idea is used to scale scores across different test forms and to normalize ratings in performance reviews.
Pediatric growth charts, such as the WHO charts used for young children, rate height and weight with z-scores (also called SD scores), which tell how many standard deviations (SD) a child is from the average.
About 2.3% of children fall outside each of the ±2 SD lines (\(z = \pm 2\)). These lines, which match the 2.3rd and 97.7th percentiles, are one of the guides doctors use to decide whether to keep an eye on growth (children grow at different rates, and the doctor makes the call after following the trend). Knowing what the "−2 SD" line stands for makes checkup explanations easier to follow.
The sizes and weights of products often vary close to a normal distribution, so turning the upper and lower spec limits into z-scores lets you estimate the defect rate. If the limits sit at the mean \(\pm 3\sigma\), about 0.3% fall outside (\(2 \times (1 - \Phi(3)) \approx 0.0027\)).
The name of the quality improvement method "Six Sigma" also comes from this z-score idea (how many σ away).
Banks and asset managers measure the risk of losses on their holdings with a measure called value at risk (VaR). If returns are assumed to follow a normal distribution, the boundary where "the loss stays within this range with 99% probability" is the z-score \(\Phi^{-1}(0.99) \approx 2.33\), that is, 2.33 standard deviations from the mean.
This "probability to z-score" conversion is at the base of risk calculations at financial institutions around the world.
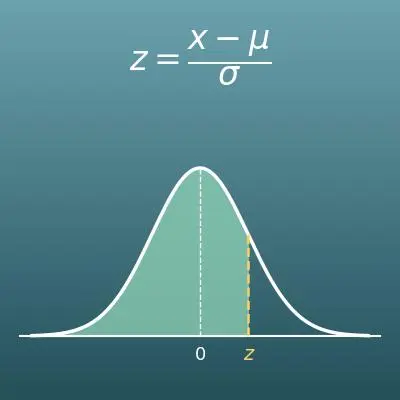
Formula and graph
Symbols and terms
Symbols
| \(z\) | zee (z-score) | A number that tells how many standard deviations a value is from the mean, found with \(z = (x - \mu) \div \sigma\). A positive value is above the mean, and a negative value is below it. On this page, a z-score that you specify, as in ② and ③, is written with a capital \(Z\). |
| \(x\) | ex | The value you measured, such as a test score or a height. It is the original value you want to turn into a z-score. |
| \(\mu\) | mu | The mean. It is where the center of the peak of the distribution sits. A Greek letter that corresponds to the English m. |
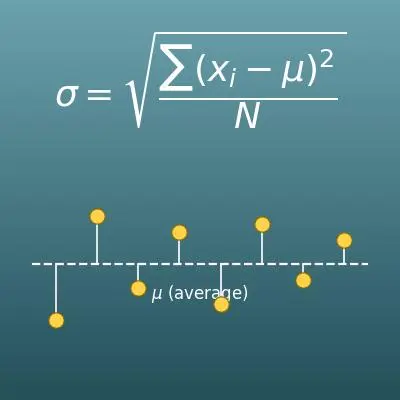
| \(\sigma\) | sigma | The standard deviation, the size of the spread of the data. The larger it is, the lower and wider the peak. A Greek letter that corresponds to the English s. |
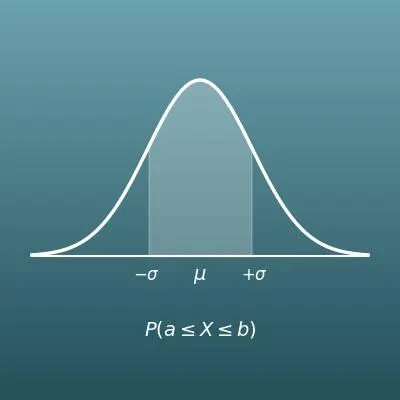
| \(\Phi(Z)\) | phi of Z | The cumulative distribution function of the standard normal distribution (mean 0, standard deviation 1). It returns the probability of a value below \(Z\), which is the area under the curve to the left of \(Z\). |
| \(\Phi^{-1}\) | phi inverse (inverse of Φ) | The function that works the other way from \(\Phi\). It takes a probability (area) and returns the z-score that gives it. (Example: \(\Phi^{-1}(0.975) \approx 1.96\)) |
| \(Z_1,\ Z_2\) | Z sub 1, Z sub 2 | The two z-scores you enter in ③. \(Z_1\) is the left (smaller) bound and \(Z_2\) is the right (larger) bound. |
Terms
| z-score (standard score) | A number with no units that tells how many standard deviations a value is from the mean. It is also called a standard score or z-value. Its biggest strength is that it puts data with different units or different maximum scores on the same ruler. |
| standardization | Turning an original value into a z-score. Once standardized, data from any normal distribution can be handled with the single standard normal distribution with mean 0 and standard deviation 1. |
| standard normal distribution | The normal distribution with mean 0 and standard deviation 1. It is the distribution of z-scores and serves as the common ruler for probability calculations with any normal distribution. |
| normal distribution | A distribution spread symmetrically around the mean in a bell shape. Many real-world data, such as test scores, heights and the weights of products, come close to this shape. |
| cumulative distribution function | A function that returns the probability of getting that value or less. For the standard normal distribution it is written \(\Phi\) (phi). It gets its name because it adds up (accumulates) the area on the left side of the curve. |
| z table (standard normal table) | A table that lists z-scores and the matching values (areas) of \(\Phi\). It is printed at the back of statistics textbooks. Way ② on this page can be used instead of a z table. |
| T-score | A z-score rescaled so that the mean is 50 and one standard deviation is 10 (T-score \(= 50 + 10 \times z\)). It is used in some psychological and educational tests. IQ scores work the same way with a mean of 100 and 15 per standard deviation. |
Good to know before you start
Here is what helps you use the calculation on this page with real understanding, not just by pressing the button.
| The mean (Grade 6) |
|
| Operations with negative numbers (Grade 7) |
|
| Data analysis and standard deviation (high school statistics) |
|
| The normal distribution and reading areas (high school statistics / AP Statistics) |
|
How to calculate it in Excel
| Value x | 75 |
| Mean μ | 65 |
| Standard dev. σ | 5 |
| z-score | =(B1-B2)/B3 |
| z-score Z | 2 |
| P(x<Z) | =NORM.S.DIST(B1,TRUE) |
| z-score Z | 1.96 |
| Φ(Z) | =NORM.S.DIST(B1,TRUE) |
| Probability between −Z and Z | =2*B2-1 |
| Left Z1 | -1 |
| Right Z2 | 0 |
| Φ(Z1) | =NORM.S.DIST(B1,TRUE) |
| Φ(Z2) | =NORM.S.DIST(B2,TRUE) |
| Probability between Z1 and Z2 | =B4-B3 |
In the first table, change the value, mean and standard deviation (B1 to B3) and B4 shows the z-score (with the example values, B4 is 2). The second table finds the probability (B2) from the z-score (B1); with the example value, B2 is about 0.97725 (97.7%).
In the third table, enter the z-score 1.96 and you get the probability between −1.96 and 1.96 (B3) of about 0.95 (95%). The fourth table is the probability between two z-scores; with the example values (−1 and 0), B5 is about 0.34134 (34.1%).
To go the other way, "from a probability to a z-score", use "=NORM.S.INV(probability)" (example: `=NORM.S.INV(0.975)` is about 1.95996).
How to calculate it in Google Sheets
| Value x | 75 |
| Mean μ | 65 |
| Standard dev. σ | 5 |
| z-score | =(B1-B2)/B3 |
| z-score Z | 2 |
| P(x<Z) | =NORMSDIST(B1) |
| z-score Z | 1.96 |
| Φ(Z) | =NORMSDIST(B1) |
| Probability between −Z and Z | =2*B2-1 |
| Left Z1 | -1 |
| Right Z2 | 0 |
| Φ(Z1) | =NORMSDIST(B1) |
| Φ(Z2) | =NORMSDIST(B2) |
| Probability between Z1 and Z2 | =B4-B3 |
The results are the same as in the Excel version: the first table gives a z-score of 2 from 75, 65 and 5, and the second gives a probability of about 0.97725 from a z-score of 2.
To find a z-score from a probability, use "=NORMSINV(probability)" (example: `=NORMSINV(0.975)` is about 1.95996).
How to calculate it in Python
import math

def phi(z):
    # Cumulative distribution function of the standard normal distribution, Φ(z) (calculated with the error function erf)
    return 0.5 * (1 + math.erf(z / math.sqrt(2)))

x = 75       # value
mean = 65    # mean
sd = 5       # standard deviation

z_score = (x - mean) / sd             # z-score
p_less_than_z = phi(z_score)          # probability of a value below the z-score, P(x<Z)

z = 1.96
p_between_minus_z_and_z = 2 * phi(z) - 1   # probability between -z and z

z1, z2 = -1, 0
p_between_z1_z2 = phi(z2) - phi(z1)        # probability between z1 and z2

print(f"z-score: {z_score}")
print(f"P(x<Z): {p_less_than_z}")
print(f"Probability between -z and z: {p_between_minus_z_and_z}")
print(f"Probability between z1 and z2: {p_between_z1_z2}")
How to write it in LaTeX and other math languages (copy and paste)
z = (x − μ) ÷ σ
z = \dfrac{x - \mu}{\sigma}
<math xmlns="http://www.w3.org/1998/Math/MathML" display="block">
<mrow>
<mi>z</mi>
<mo>=</mo>
<mfrac>
<mrow><mi>x</mi><mo>−</mo><mi>μ</mi></mrow>
<mi>σ</mi>
</mfrac>
</mrow>
</math>
z = (x - mu)/sigma
(x - mu)/sigma
z := (x - mu)/sigma;
z = (x - mu)/sigma;
z = (x-μ)/σ
P(x<Z) = Φ(Z)
P(x<Z) = \Phi(Z)
<math xmlns="http://www.w3.org/1998/Math/MathML" display="block">
<mrow>
<mi>P</mi><mo>(</mo><mi>x</mi><mo><</mo><mi>Z</mi><mo>)</mo>
<mo>=</mo>
<mi>Φ</mi><mo>(</mo><mi>Z</mi><mo>)</mo>
</mrow>
</math>
P(x<Z) = Phi(Z)
CDF[NormalDistribution[0, 1], Z]
with(Statistics): CDF(RandomVariable(Normal(0, 1)), Z);
p = normcdf(Z);
P(x<Z) = Φ(Z)
P(−Z<x<Z) = 2Φ(Z) − 1
P(-Z<x<Z) = 2\Phi(Z) - 1
<math xmlns="http://www.w3.org/1998/Math/MathML" display="block">
<mrow>
<mi>P</mi><mo>(</mo><mo>−</mo><mi>Z</mi><mo><</mo><mi>x</mi><mo><</mo><mi>Z</mi><mo>)</mo>
<mo>=</mo>
<mn>2</mn><mi>Φ</mi><mo>(</mo><mi>Z</mi><mo>)</mo><mo>−</mo><mn>1</mn>
</mrow>
</math>
P(-Z<x<Z) = 2 Phi(Z) - 1
2 CDF[NormalDistribution[0, 1], Z] - 1
with(Statistics): 2*CDF(RandomVariable(Normal(0, 1)), Z) - 1;
p = 2*normcdf(Z) - 1;
P(-Z<x<Z) = 2Φ(Z) - 1
P(Z₁<x<Z₂) = Φ(Z₂) − Φ(Z₁)
P(Z_1<x<Z_2) = \Phi(Z_2) - \Phi(Z_1)
<math xmlns="http://www.w3.org/1998/Math/MathML" display="block">
<mrow>
<mi>P</mi><mo>(</mo><msub><mi>Z</mi><mn>1</mn></msub><mo><</mo><mi>x</mi><mo><</mo><msub><mi>Z</mi><mn>2</mn></msub><mo>)</mo>
<mo>=</mo>
<mi>Φ</mi><mo>(</mo><msub><mi>Z</mi><mn>2</mn></msub><mo>)</mo>
<mo>−</mo>
<mi>Φ</mi><mo>(</mo><msub><mi>Z</mi><mn>1</mn></msub><mo>)</mo>
</mrow>
</math>
P(Z_1<x<Z_2) = Phi(Z_2) - Phi(Z_1)
CDF[NormalDistribution[0, 1], Z2] - CDF[NormalDistribution[0, 1], Z1]
with(Statistics): CDF(RandomVariable(Normal(0, 1)), Z2) - CDF(RandomVariable(Normal(0, 1)), Z1);
p = normcdf(Z2) - normcdf(Z1);
P(Z1<x<Z2) = Φ(Z2) - Φ(Z1)
How to have ChatGPT do the calculation
You are a statistics calculation assistant. Do the following calculation by actually running Python code, and base your answer only on the numbers from the execution result (do not answer by mental math or guessing).

Someone scored 75 points on a test with a mean of 65 points and a standard deviation of 5 points.
1. Find this person's z-score.
2. Find the probability of scoring below that value, P(x<Z) (use the cumulative distribution function Φ of the standard normal distribution; you may use Python's standard library, such as math.erf or statistics.NormalDist).
3. Also find the probability that a z-score falls between −1.96 and 1.96.

Show the formulas you used and the numbers from the execution result.
How to Use
-
1Enter your numbersType the numbers you want to calculate with into the input fields
-
2CalculatePress the "Calculate" button
-
3Check the resultThe result appears on the spot. The same page also explains the idea behind the calculation and the formula
DataChef Features

No technical knowledge required.
Intuitive and user-friendly operation.
Can be used without registering personal information.
Automatic file deletion by clicking "download".
and rapid file conversion.
No attribution required.
No need to contact us for commercial use permission.
Related Features
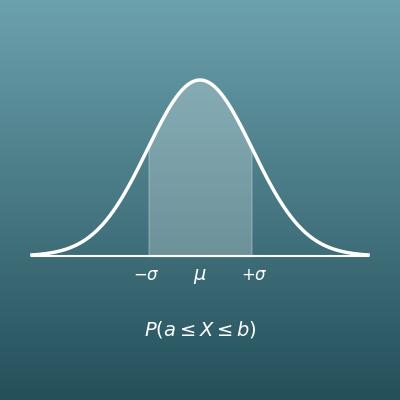
Normal Distribution Probability Calculator
From the mean and standard deviation, find the probability of falling in a range or the top what percent
Standard Deviation Calculator for Population and Sample
From a list of numbers, find the population and sample standard deviation, the variance and the mean
Probability of Two Events (And, Or, Neither)
From two probabilities, find the probability that both happen, that at least one happens, and more