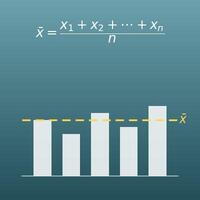
Enter the numbers whose spread you want to measure, separated by commas (,). The population standard deviation σ and the sample standard deviation s are calculated together with the mean, the variances and the sum of squared deviations.
Table of Contents
-
What you can do on this page
-
What is this calculation used for?
-
How to Use
-
Formulas and figures
-
Symbols and terms
-
Good to know before you start
-
How to calculate it in Excel
-
How to calculate it in Google Sheets
-
How to calculate it in Python
-
How to write it in LaTeX and other math languages (copy and paste)
-
How to have ChatGPT do the calculation
-
DataChef Features
-
Related Features
-
NumberChef Calculators List
What you can do on this page
- Enter numbers separated by commas (,) and you get the standard deviation on the spot
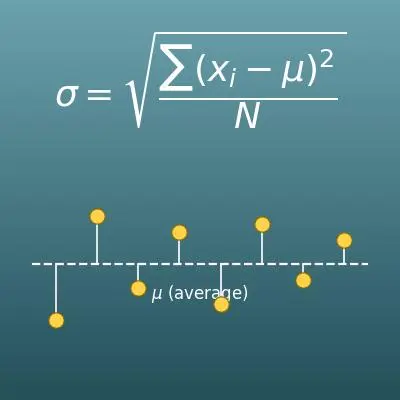
- Both the population standard deviation \(\sigma\) (divide by \(N\)) and the sample standard deviation \(s\) (divide by \(N-1\)) are shown together
- The mean \(\mu\), the sum of squared deviations \(\sum (x_i-\mu)^2\) and the variances \(\sigma^2,\ s^2\) are calculated too, so you can follow every step at a glance
- A plain-language explanation of the formulas and copy-and-paste formulas for Excel, Google Sheets and Python are all on this page
What is this calculation used for?
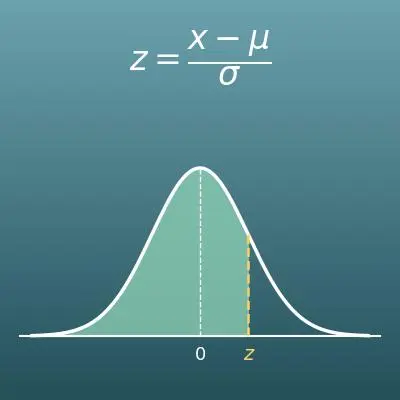
A z-score (standard score) tells you how far a score is from the mean, measured in standard deviations: \(z = \dfrac{x - \text{mean}}{\text{standard deviation}}\). The standard deviation is right there in the denominator.
If the class mean is 70 and the standard deviation is 10, a score of 85 has \(z = (85 - 70) \div 10 = 1.5\), which is 1.5 standard deviations above the mean. Teachers who "grade on a curve" and standardized test reports use this same idea. It also explains why the same score can stand out more on a test where scores are tightly packed (small spread).
No matter how precisely they are made, screw lengths and part weights vary a little. Factories measure this variation with the standard deviation and manage the process so that "the mean ± 3 standard deviations" stays within the customer's specifications.
A smaller standard deviation means more consistent, better products. The standard deviation is so basic that improving quality can almost be described as the work of making it smaller.
Two investments may both have an average return of 5%, but the one whose returns have a larger standard deviation has some years of big gains and some years of big losses, so it is judged to be riskier.
In finance, the standard deviation of returns is called volatility, and it is the most common measure of risk. For important money decisions, look at the spread (the standard deviation) as well as the average.
Two cities may have the same average yearly temperature. If the standard deviation of their monthly temperatures is small, the city is mild all year; if it is large, summer and winter are very different.
The standard deviation turns "steady or changeable" into a number, which the average alone cannot show. It is used to compare climates and to plan crops and tourism.
The reference range shown on blood test results is sometimes set by collecting data from many healthy people and taking about "the mean ± 2 standard deviations" (in practice, each test uses a method that fits the shape of its distribution).
Knowing about the standard deviation helps you stay calm: being slightly outside the reference range does not automatically mean you are ill, because some healthy people fall outside it too.
Formulas and figures
Symbols and terms
Symbols
| \(x_1, x_2, \ldots, x_N\) | x sub 1, x sub 2, …, x sub N | The individual values whose spread you want to measure. (Example - the test scores of 8 students) |
| \(N\) | N | The number of values. (Example - for 8 students, \(N = 8\)) |
| \(\mu\) | mu | The mean. This Greek letter stands for the mean of a population. The mean of a sample is written \(\bar{x}\) (x-bar), but it is calculated the same way. |
| \(x_i - \mu\) | x sub i minus mu | The deviation. It shows how far each value is from the mean. |
| \(S\) | S | The sum of squared deviations, \(\sum (x_i-\mu)^2\), found by squaring each deviation and adding them all up. The variance and the standard deviation are built from it. |
| \(\sigma^2\) | sigma squared | The population variance, the sum of squared deviations divided by the count \(N\). |
| \(\sigma\) | sigma | The population standard deviation, the square root of the population variance. It is the best-known symbol for spread. |
| \(s^2\) | s squared | The sample variance (unbiased sample variance), the sum of squared deviations divided by \(N-1\). |
| \(s\) | s | The sample standard deviation, the square root of the sample variance. |
| \(\sum\) | sigma (summation sign) | A symbol that means "add them all up". \(\sum_{i=1}^{N} x_i\) is the sum from \(x_1\) to \(x_N\). |
Terms
| standard deviation | A number that shows how spread out the data is around the mean. It is the square root of the variance, and because its unit is the same as the data, it works well as a guide to "the typical distance from the mean". It is the most common measure of spread. |
| variance | The average of the squared deviations (the differences between each value and the mean). It shows how large the spread is, but its unit is squared, so it is usually turned into the standard deviation by taking the square root. |
| deviation | The difference between a value and the mean (\(x_i - \mu\)). Positive means above the mean and negative means below it. Adding them all up as they are always gives 0, so they are squared before use. |
| sum of squared deviations | The deviations squared and all added up. The variance and the standard deviation are all built from this value. |
| population | The whole group you want to study. If your data is this whole group, use the population standard deviation \(\sigma\). |
| sample | A part of the data taken from a population (the whole group). When you estimate the spread of the whole group from a sample, use the sample standard deviation \(s\). |
| unbiased sample variance | The variance used to estimate the variance of a population from a sample. Divide the sum of squared deviations by \(N-1\). Dividing by \(N\) would make the spread of the population come out too small, so dividing by one less corrects it. |
| Bessel's correction | The correction of dividing by \(N-1\) instead of \(N\) in the sample variance. \(N-1\) is also called the degrees of freedom. |
Good to know before you start
Here is what helps you use the calculation on this page with real understanding, not just by pressing the button.
| The mean (Grade 6) |
|
| Negative numbers and parentheses (Grades 6–7) |
|
| Exponents (Grade 6) |
|
| Square roots (Grade 8) |
|
| Distribution and spread of data (Grade 6 to high school) |
|
How to calculate it in Excel
| Value 1 | 10 |
| Value 2 | 12 |
| Value 3 | 23 |
| Value 4 | 23 |
| Value 5 | 16 |
| Value 6 | 23 |
| Value 7 | 21 |
| Value 8 | 16 |
| Count N | =COUNT(B1:B8) |
| Sum Σx | =SUM(B1:B8) |
| Mean μ | =AVERAGE(B1:B8) |
| Value 1 | 10 |
| Value 2 | 12 |
| Value 3 | 23 |
| Value 4 | 23 |
| Value 5 | 16 |
| Value 6 | 23 |
| Value 7 | 21 |
| Value 8 | 16 |
| Sum of squared deviations S | =DEVSQ(B1:B8) |
| Value 1 | 10 |
| Value 2 | 12 |
| Value 3 | 23 |
| Value 4 | 23 |
| Value 5 | 16 |
| Value 6 | 23 |
| Value 7 | 21 |
| Value 8 | 16 |
| Population variance σ² | =VARP(B1:B8) |
| Population standard deviation σ | =STDEVP(B1:B8) |
| Value 1 | 10 |
| Value 2 | 12 |
| Value 3 | 23 |
| Value 4 | 23 |
| Value 5 | 16 |
| Value 6 | 23 |
| Value 7 | 21 |
| Value 8 | 16 |
| Sample variance s² | =VAR(B1:B8) |
| Sample standard deviation s | =STDEV(B1:B8) |
The first table shows 18 for the mean μ. The population standard deviation σ in the third table is about 4.899, and the sample standard deviation s in the fourth table is about 5.237.
To use a different number of values, add (or remove) rows of numbers, then change "B1:B8" in the formulas to your actual data range (for 10 values, B1:B10).
STDEVP and VARP, with a "P", are for a population (divide by N). STDEV and VAR, without the "P", are for a sample (divide by N − 1). DEVSQ gives the sum of squared deviations in one step.
How to calculate it in Google Sheets
| Value 1 | 10 |
| Value 2 | 12 |
| Value 3 | 23 |
| Value 4 | 23 |
| Value 5 | 16 |
| Value 6 | 23 |
| Value 7 | 21 |
| Value 8 | 16 |
| Count N | =COUNT(B1:B8) |
| Sum Σx | =SUM(B1:B8) |
| Mean μ | =AVERAGE(B1:B8) |
| Value 1 | 10 |
| Value 2 | 12 |
| Value 3 | 23 |
| Value 4 | 23 |
| Value 5 | 16 |
| Value 6 | 23 |
| Value 7 | 21 |
| Value 8 | 16 |
| Sum of squared deviations S | =DEVSQ(B1:B8) |
| Value 1 | 10 |
| Value 2 | 12 |
| Value 3 | 23 |
| Value 4 | 23 |
| Value 5 | 16 |
| Value 6 | 23 |
| Value 7 | 21 |
| Value 8 | 16 |
| Population variance σ² | =VARP(B1:B8) |
| Population standard deviation σ | =STDEVP(B1:B8) |
| Value 1 | 10 |
| Value 2 | 12 |
| Value 3 | 23 |
| Value 4 | 23 |
| Value 5 | 16 |
| Value 6 | 23 |
| Value 7 | 21 |
| Value 8 | 16 |
| Sample variance s² | =VAR(B1:B8) |
| Sample standard deviation s | =STDEV(B1:B8) |
In Google Sheets too, use STDEVP and VARP for a population and STDEV and VAR for a sample.
How to calculate it in Python
import statistics

numbers = [10, 12, 23, 23, 16, 23, 21, 16]  # the numbers whose spread you want to measure

mean = statistics.mean(numbers)               # mean μ
pstdev = statistics.pstdev(numbers)           # population standard deviation σ (divide by N)
pvariance = statistics.pvariance(numbers)     # population variance σ²
sstdev = statistics.stdev(numbers)            # sample standard deviation s (divide by N-1)
svariance = statistics.variance(numbers)      # sample variance s²

print(f"Count: {len(numbers)} / Sum: {sum(numbers)} / Mean: {mean}")
print(f"Population variance σ²: {pvariance} / Population SD σ: {pstdev}")
print(f"Sample variance s²: {svariance} / Sample SD s: {sstdev}")
How to write it in LaTeX and other math languages (copy and paste)
μ = Σxᵢ ÷ N
\mu = \frac{x_1 + x_2 + \cdots + x_N}{N}
<math xmlns="http://www.w3.org/1998/Math/MathML" display="block">
<mrow>
<mi>μ</mi>
<mo>=</mo>
<mfrac>
<mrow>
<msub><mi>x</mi><mn>1</mn></msub>
<mo>+</mo>
<msub><mi>x</mi><mn>2</mn></msub>
<mo>+</mo>
<mo>⋯</mo>
<mo>+</mo>
<msub><mi>x</mi><mi>N</mi></msub>
</mrow>
<mi>N</mi>
</mfrac>
</mrow>
</math>
mu = (x_1 + x_2 + cdots + x_N) / N
Mean[data]
mu := add(x[i], i = 1 .. N)/N;
mu = mean(x);
μ = (x_1 + x_2 + ⋯ + x_N)/N
S = Σ(xᵢ − μ)²
S = \sum_{i=1}^{N} (x_i - \mu)^2
<math xmlns="http://www.w3.org/1998/Math/MathML" display="block">
<mrow>
<mi>S</mi>
<mo>=</mo>
<munderover>
<mo>∑</mo>
<mrow><mi>i</mi><mo>=</mo><mn>1</mn></mrow>
<mi>N</mi>
</munderover>
<msup>
<mrow><mo>(</mo><msub><mi>x</mi><mi>i</mi></msub><mo>−</mo><mi>μ</mi><mo>)</mo></mrow>
<mn>2</mn>
</msup>
</mrow>
</math>
S = sum_(i=1)^N (x_i - mu)^2
Total[(data - Mean[data])^2]
S := add((x[i] - mu)^2, i = 1 .. N);
S = sum((x - mean(x)).^2);
S = ∑_(i=1)^N (x_i − μ)^2
σ² = S ÷ N, s² = S ÷ (N − 1)
\sigma^2 = \frac{S}{N}, \qquad s^2 = \frac{S}{N-1}
<math xmlns="http://www.w3.org/1998/Math/MathML" display="block">
<mrow>
<msup><mi>σ</mi><mn>2</mn></msup>
<mo>=</mo>
<mfrac><mi>S</mi><mi>N</mi></mfrac>
<mo>,</mo>
<mspace width="1em"/>
<msup><mi>s</mi><mn>2</mn></msup>
<mo>=</mo>
<mfrac><mi>S</mi><mrow><mi>N</mi><mo>−</mo><mn>1</mn></mrow></mfrac>
</mrow>
</math>
sigma^2 = S/N, s^2 = S/(N-1)
popVar = S/n; sampleVar = Variance[data] (* N is a built-in function in Mathematica, so the count is named n *)
sigma2 := S/N; s2 := S/(N - 1);
popVar = S/N; sampleVar = var(x);
σ^2 = S/N, s^2 = S/(N−1)
σ = √(σ²), s = √(s²)
\sigma = \sqrt{\sigma^2} = \sqrt{\dfrac{S}{N}}, \qquad s = \sqrt{s^2} = \sqrt{\dfrac{S}{N-1}}
<math xmlns="http://www.w3.org/1998/Math/MathML" display="block">
<mrow>
<mi>σ</mi>
<mo>=</mo>
<msqrt><mfrac><mi>S</mi><mi>N</mi></mfrac></msqrt>
<mo>,</mo>
<mspace width="1em"/>
<mi>s</mi>
<mo>=</mo>
<msqrt><mfrac><mi>S</mi><mrow><mi>N</mi><mo>−</mo><mn>1</mn></mrow></mfrac></msqrt>
</mrow>
</math>
sigma = sqrt(S/N), s = sqrt(S/(N-1))
popSD = Sqrt[S/n]; sampleSD = StandardDeviation[data] (* N is a built-in function in Mathematica, so the count is named n *)
sigma := sqrt(S/N); s := sqrt(S/(N - 1));
popSD = sqrt(S/numel(x)); sampleSD = std(x);
σ = √(S/N), s = √(S/(N−1))
How to have ChatGPT do the calculation
You are a statistics calculation assistant. Do the following calculation by actually running Python code, and base your answer only on the numbers from the execution result (do not answer by mental math or guessing).

For the following data, find each of the values below.
Data: 10, 12, 23, 23, 16, 23, 21, 16
1. The count, the sum and the mean
2. The sum of squared deviations (each value's difference from the mean, squared and all added up)
3. The population variance σ² (divide by N) and the population standard deviation σ
4. The sample variance s² (divide by N − 1) and the sample standard deviation s

Show the formulas you used and the numbers from the execution result.
How to Use
-
1Enter your numbersType the numbers you want to calculate with into the input fields
-
2CalculatePress the "Calculate" button
-
3Check the resultThe result appears on the spot. The same page also explains the idea behind the calculation and the formula
DataChef Features

No technical knowledge required.
Intuitive and user-friendly operation.
Can be used without registering personal information.
Automatic file deletion by clicking "download".
and rapid file conversion.
No attribution required.
No need to contact us for commercial use permission.
Related Features
Average Calculator (Mean)
Calculates the average, median, geometric mean and more from comma-separated numbers
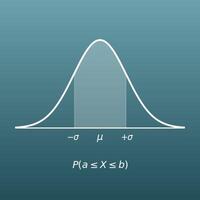
Normal Distribution Probability Calculator
Find the probability of falling in a given range from the mean and standard deviation

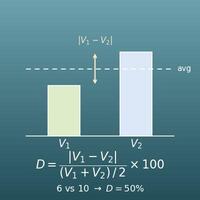
Percent Difference Calculator
Shows the difference between two values as a percentage of their average
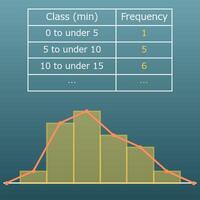
Frequency Distribution Table Calculator (Relative and Cumulative Frequency, Histogram)
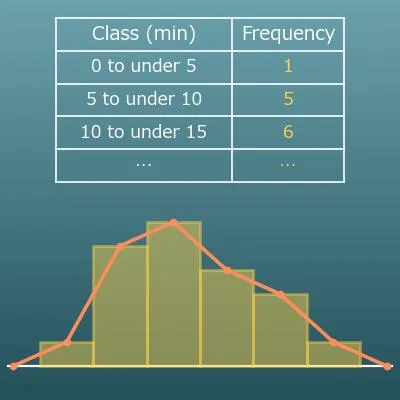
Builds a frequency distribution table from raw data, with relative and cumulative frequency, an estimated mean from class midpoints, a histogram and a frequency polygon